How AI Models Learn Like a Brain
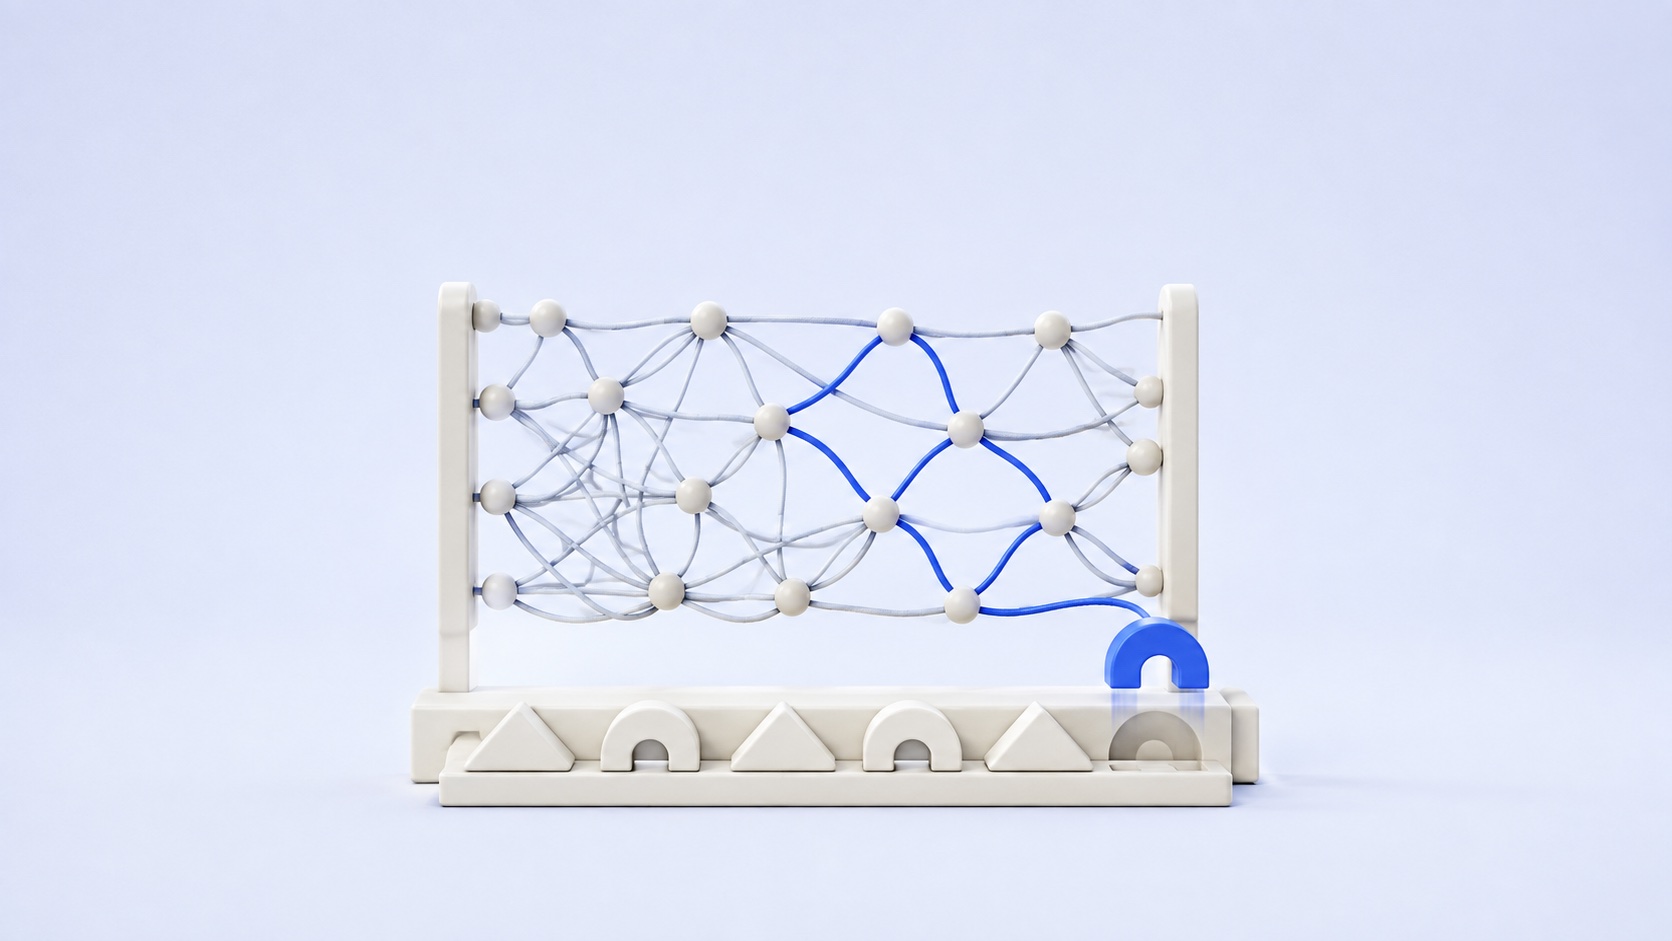
A large language model starts out as a tangle of noise. Picture a bowl of spaghetti, except every strand is a connection wired to another strand at random, with no pattern to any of it. Feed that tangle a sentence and it answers with gibberish. Nobody has written rules into it about what a question needs, or what a good answer looks like. Whatever it eventually comes to know has to be trained into it from nothing.
That is an odd way to describe something people call software. Ordinary software is a list of instructions that a person wrote. When a user asks for one type of thing, the software does another specific type of thing, for a set number of steps, then stops. A large language model has no such list anywhere inside it. There is no line of code that spells out what to do with a question about taxes, or a request for a poem. What sits inside it instead is a neural network.
A neural network is loosely modeled on a brain. A brain is a web of neurons passing signals to each other, and over the course of a life, certain patterns of firing get reinforced. A pattern that leads to something rewarding fires more easily the next time it has the chance. A pattern that leads to pain, like a hand pulling back from a hot stove, gets weakened, so it fires less easily. Nobody designs this behavior directly. It builds up on its own, through years of repeated reinforcement, until a person ends up with the habits and instincts they carry into adulthood.
Artificial neural networks copy that same process, minus the biology. A new one starts out as a huge number of randomly generated connections, called parameters, and none of them has ever been reinforced or weakened by anything. That is the whole reason an untrained network only produces gibberish. Nothing inside it yet points toward a right answer, because nothing inside it has been corrected even once. In today’s largest systems, those connections are reported to number more than a trillion, far too many for any engineer to set by hand.
No engineer sets a trillion connections by hand, so turning that tangle into something useful has to happen a different way, through a stage called pretraining. Engineers collect a massive amount of ordinary text from the internet and feed it to the network in small pieces. They show it one piece of text as a starting point, and the network answers with its best guess at what comes next. Early on, that guess is close to random. The guess then gets checked against the word that comes next in the original text. The connections behind a good guess get strengthened. The connections behind a bad guess get weakened. That single adjustment, repeated, is the same reinforcement that shapes a brain.
The entire game during this stage of training is to predict the next word, get corrected, adjust a little, then try again on the next piece of text. Repeated across billions of pieces of text, that one exercise is what teaches the network grammar, facts, and the patterns that make an answer sound like a real answer instead of noise. Nobody tells the network any of this directly, the way a teacher might explain a grammar rule. It arrives at all of it by getting nudged, one predicted word at a time, toward whatever word comes next in real writing, over and over, until the nudging adds up to something that reads like language.
The result is a system that never received a single instruction, only a long series of corrections. What looks like understanding in a finished model is a tangle of once-random connections that got adjusted, one predicted word at a time, until gibberish turned into language that reads like it was written on purpose. Nobody planned that outcome in advance. It emerged from the same blind process that shapes a brain: try, get corrected, adjust, repeat, until a habit of guessing correctly is all that is left.
Sources
The Decoder, GPT-4 Has More Than a Trillion Parameters, the-decoder.com